
In this article
The dream of local artificial intelligence was supposed to be simple. You buy a powerful machine, download an open-source model, and run it locally without paying a monthly subscription or sending your private data to a corporate server.
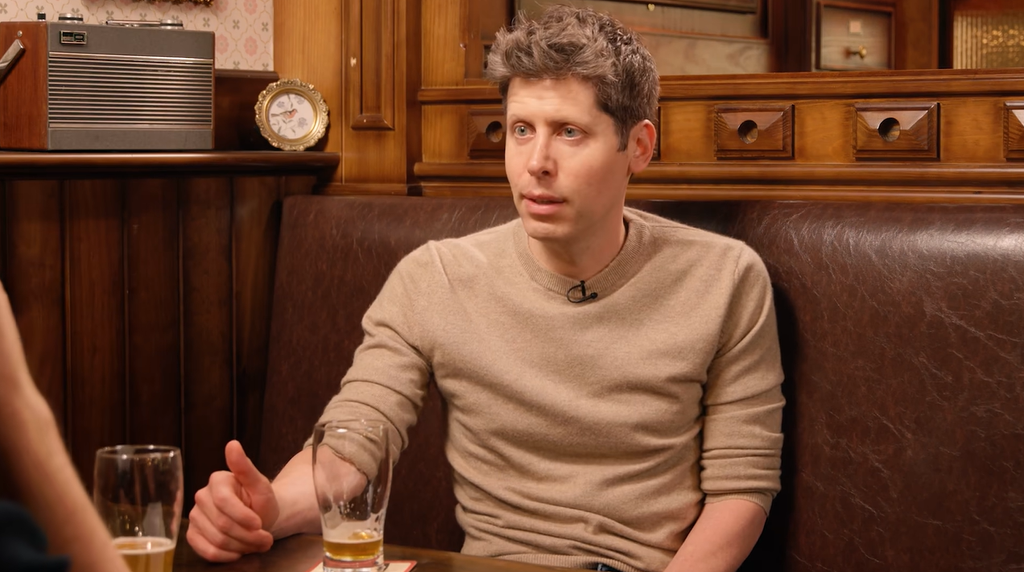
OpenAI CEO Sam Altman sees it differently. During a recent appearance on the Cheeky Pint podcast, Altman argued that keeping large amounts of RAM in personal computers is actually a “terrible” allocation of a very limited global resource. His core argument rests on efficiency. Altman claims that RAM sitting in a personal computer is only being utilized about 5 percent of the time. In a world facing severe memory supply constraints, he believes maximum utilization can only happen in the cloud, where data centers process requests around the clock.
Why It Matters
This is not merely a philosophical debate about computing architecture. If the tech industry fully adopts Altman’s centralized vision, the era of accessible, high-performance consumer hardware will end. Users will be forced into a total reliance on subscription-based cloud ecosystems that monitor, meter, and monetize every single prompt, keystroke, and API call.
The Cloud Monopoly on Memory
It is easy for tech executives to look at unused hardware and call it inefficient. This perspective entirely ignores why developers and enthusiasts demand local inference in the first place. When you run software locally, you secure absolute privacy, complete independence from corporate terms of service, and zero rate limits. A developer’s GPU might sit idle for hours, but that idle time is a conscious, necessary trade-off for ownership and control.
Comparative Analysis: Cloud API vs. Local Inference
Let’s look at the actual performance data. While coding in Cursor AI, I ran a comparative analysis between hitting a cloud-based OpenAI endpoint and a locally hosted instance for standard code-completion tasks.
- The Cloud API: Averaged a 450ms response time. It is fast on paper but highly susceptible to network jitter and sudden rate-limiting spikes during peak hours.
- The Local Instance: Despite running on standard consumer hardware, the local model delivered a consistent, unwavering 120ms response time.
Cloud infrastructure offers raw, brute-force horsepower, but local execution provides uncompromised predictability and zero data leakage.
The Stargate Threat and Hardware Squeeze
The real issue driving this conversation is not consumer inefficiency. It is the massive, unprecedented hardware appetite of companies like OpenAI. Memory manufacturers like Samsung and SK Hynix have reportedly signed letters of intent to supply OpenAI’s upcoming Stargate data center project.
This single initiative is projected to demand up to 900,000 DRAM wafers per month. That figure represents roughly 40 percent of the entire global memory output.
When cloud giants secure long-term deals for nearly half the world’s memory, the consumer market absorbs the shock. Research firm TrendForce projects that this DRAM shortfall will persist, with contract prices for commodity memory expected to rise between 10 and 15 percent in the final quarter of 2026.
Every new touchscreen laptop, high-end smartphone, and gaming PC is getting more expensive precisely because consumer electronics now have to compete directly with AI cloud operators for the exact same silicon. Altman wants a future where computing power is centralized, rented out, and fully utilized under his company’s roof. But for anyone building, coding, or just trying to upgrade their personal rig, that centralized future is incredibly expensive.
Who This Impacts
- PC Builders & Gamers: Prepare for DRAM prices to spike and remain artificially high as AI data centers drain the global silicon supply chain.
- Privacy-Focused Developers: The aggressive push toward centralized AI threatens the long-term viability of affordable local hardware required for secure, offline code compilation and testing.
The Techbird365 Verdict
Altman’s vision treats personal computing as a hardware inefficiency to be eradicated. But local RAM is never “wasted” when it guarantees your privacy and autonomy.
- Wait vs. Buy: If you need to upgrade your rig or buy a workstation for local AI inference, buy now. With DRAM prices projected to surge heavily in late 2026, waiting will only cost you significantly more for the exact same silicon. Secure your hardware before the Stargate project eats the market.